


Updated Mar-2026 Official licence for DA0-001 Certified by DA0-001 Dumps PDF
Grab latest Amazon DA0-001 Dumps as PDF Updated on 2026
NEW QUESTION # 231
Refer to exhibit.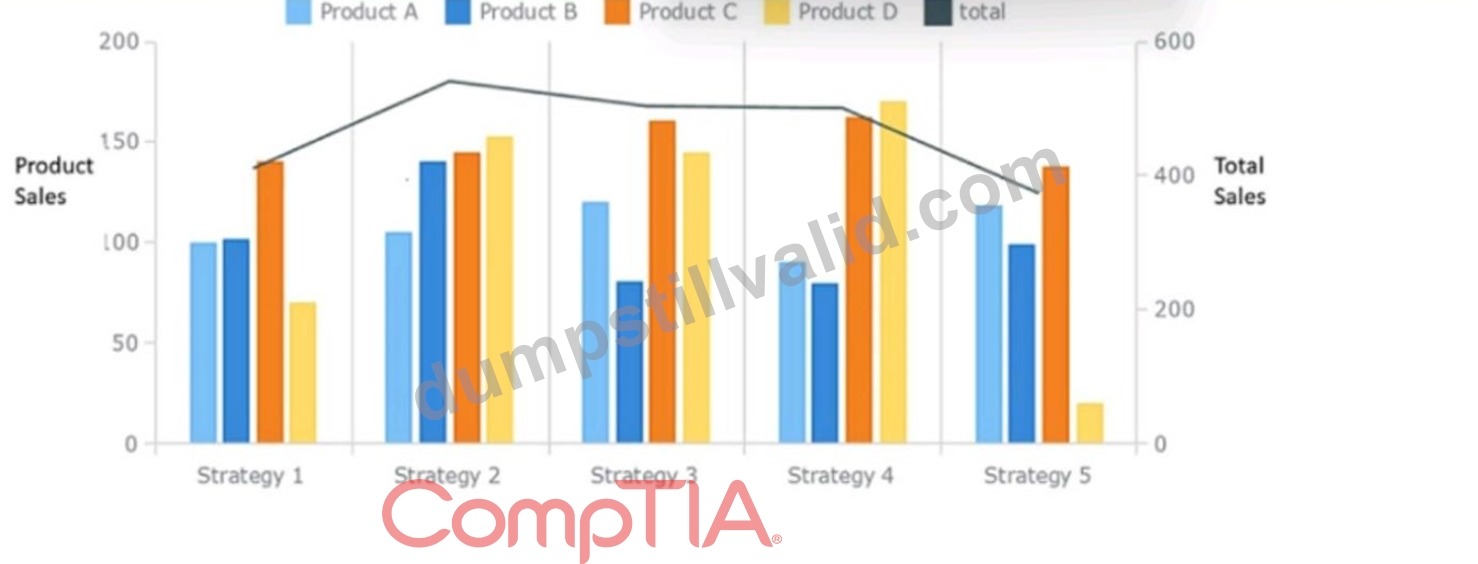
Which of the following summary statements upholds integrity in data reporting?
- A. Product D should be promoted more than the other products in all strategies.
- B. While Strategy 2 does not result in the highest sales of Product D. over all products it appears to be the most effective.
- C. Sales are approximately equal for Product A and Product B across all strategies.
- D. Strategy 4 provides the best sales in comparison to other strategies.
Answer: B
Explanation:
Answer C) While Strategy 2 does not result in the highest sales of Product D. over A summary statement that upholds integrity in data reporting should be accurate, unbiased, and supported by evidence. Option C is the only statement that meets these criteria, as it reflects the data shown in the bar graph without exaggerating or distorting it. Option C also acknowledges the limitation of the statement by using the word "appears", which indicates that there may be other factors or variables that affect the sales performance.
Option A is inaccurate, as sales are not approximately equal for Product A and Product B across all strategies. Product A has higher sales than Product B in strategies 1, 3, and 5, while Product B has higher sales than Product A in strategies 2 and 4.
Option B is biased, as it does not consider the sales of different products in each strategy. Strategy 4 provides the best sales for Product B, but not for the other products. Strategy 5 has the highest total sales across all products, as shown by the black line graph.
Option D is unsupported by evidence, as it does not explain why Product D should be promoted more than the other products in all strategies. Product D has the lowest sales among all products in strategies 1, 3, and 4, and only slightly higher sales than Product C in strategies 2 and 5.
NEW QUESTION # 232
A data analyst is designing a dashboard that will provide a story of sales and determine which site is providing the highest sales volume per customer The analyst must choose an appropriate chart to include in the dashboard. The following data is available: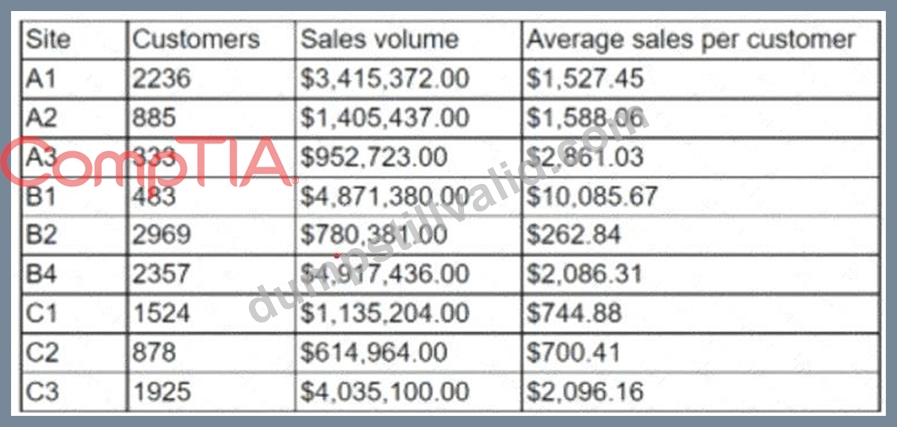
Which of the following types of charts should be considered?
- A. Include a scatter chart using sales volume and average sales per customer.
- B. Include a column chart using the site and sales to average sales per customer.
- C. Include a pie chart using the site and sales to average sales per customer.
- D. Include a line chart using the site and average sales per customer.
Answer: B
Explanation:
The best type of chart to display the data is D. Include a column chart using the site and sales to average sales per customer.
A column chart is a good choice for comparing categorical data with numerical data, such as the site and sales to average sales per customer. A column chart can show the relative differences between the sites and highlight the site with the highest sales volume per customer. A column chart can also be easily labeled and formatted to make the data clear and understandable.
A line chart is not suitable for this data, because it is used to show trends or changes over time, which is not relevant for the site and sales to average sales per customer data. A line chart would also be confusing and misleading, as it would imply a connection or correlation between the sites that does not exist.
A pie chart is also not a good choice for this data, because it is used to show the proportion of a whole, not the comparison of different categories. A pie chart would also be difficult to read and interpret, as it would require labels or legends to identify the sites and their sales to average sales per customer. A pie chart would also not be able to show the exact values of the sales to average sales per customer, only their relative sizes.
A scatter chart is another inappropriate option for this data, because it is used to show the relationship or correlation between two numerical variables, not between a categorical and a numerical variable. A scatter chart would also be cluttered and unclear, as it would plot each site as a point on a coordinate plane, without any labels or axes. A scatter chart would also not be able to show the differences or rankings between the sites and their sales to average sales per customer.
NEW QUESTION # 233
Which of the following data types best describe 4Ac1? (Select two).
- A. Symbolic
- B. Float
- C. String
- D. Numeric
- E. Boolean
- F. Alphanumeric
Answer: C,F
Explanation:
The term '4Ac1' is a combination of numbers and letters, which fits the definition of an alphanumeric string. Alphanumeric refers to a character set that contains both letters and numbers. In data analytics and programming, such a value is typically treated as a string, which is a sequence of characters. Strings can include letters, digits, and various other symbols.
A numeric data type would only include numbers, and a float is a specific kind of numeric data type that includes decimal points, neither of which applies to '4Ac1'. A boolean data type represents one of two values: true or false. Since '4Ac1' does not represent a true or false value, it cannot be classified as boolean. Lastly, symbolic is not a standard data type in the context of programming and data analytics.
Reference:
Understanding Python 3 data types1.
Basic Data Types in Python2.
Java Data Types3.
NEW QUESTION # 234
A data profiling rule checks the quality of all email addresses in a database. The rule returns a value with the number of email addresses that conformed to the rule. Which of the following options describes this value?
- A. Columns passed
- B. Rows failed
- C. Columns failed
- D. Rows passed
Answer: D
Explanation:
Data profiling rules are often applied row by row to assess data quality. In this scenario:
* Each row represents one record (e.g., one customer, one user).
* The email rule checks whether each email field conforms to a specified pattern/format (e.g., contains
@, valid domain, no illegal characters).
The result described in the question is:
* A count of how many records (rows) had an email that conformed to the rule.
This corresponds to "rows passed" - i.e., the number of rows that passed the data quality check.
Why the other options are incorrect:
* Columns passed (A): Would refer to how many columns/fields in the dataset passed a profiling rule, which is not what's described (the rule is applied to one column: email).
* Rows failed (C): Would be the count of records that did not conform, which is the opposite of what's stated ("conformed to the rule").
* Columns failed (D): Again, column-level evaluation, not row-level.
Therefore, the returned value is best described as Rows passed (B).
CompTIA Data+ Reference (concept alignment):
* DA0-001 Exam Objectives - Domain: Data Quality (profiling data and interpreting pass/fail metrics).
* CompTIA Data+ Official Study Guide - sections on data profiling metrics and the distinction between row-level and column-level quality checks.
NEW QUESTION # 235
A customer's telephone number is in the format 123-456-7890. Which of the following data types is used for the phone number?
- A. Number
- B. Text
- C. Date
- D. Boolean
Answer: B
Explanation:
A telephone number, despite being composed of digits, is not used for calculations and often includes formatting characters such as hyphens (-). Therefore, the most appropriate data type for a telephone number is Text (or VARCHAR in SQL databases), which can accommodate various formats and lengths, and preserve leading zeros that might be present in some phone numbers. Storing phone numbers as numeric data types would strip away any formatting and could lead to the loss of significant leading digits (like zeros in international numbers).
* Boolean is a binary data type and only represents true or false values.
* Date is a data type used for dates.
* Number could technically store phone numbers, but it is not suitable due to the reasons mentioned above.
References:
* Best Practices for Storing Phone Numbers1
* Data Types in SQL for Phone Numbers2
NEW QUESTION # 236
Different people manually type a series of handwritten surveys into an online database. Which of the following issues will MOST likely arise with this data? (Choose two.)
- A. Data manipulation
- B. Data bias
- C. Data accuracy
- D. Data constraints
- E. Data consistency
- F. Data attribute limitations
Answer: C,E
Explanation:
Explanation
Data accuracy refers to the extent to which the data is correct, reliable, and free of errors. When different people manually type a series of handwritten surveys into an online database, there is a high chance of human error, such as typos, misinterpretations, omissions, or duplications. These errors can affect the quality and validity of the data and lead to incorrect or misleading analysis and decisions.
Data consistency refers to the extent to which the data is uniform and compatible across different sources, formats, and systems. When different people manually type a series of handwritten surveys into an online database, there is a high chance of inconsistency, such as different spellings, abbreviations, formats, or standards. These inconsistencies can affect the integration and comparison of the data and lead to confusion or conflicts.
Therefore, to ensure data quality, it is important to have clear and consistent rules and procedures for data entry, validation, and verification. It is also advisable to use automated tools or methods to reduce human error and inconsistency.
NEW QUESTION # 237
A data analyst needs to collect a similar proportion of data from every state. Which of the following sampling methods would be the most appropriate?
- A. Random sampling
- B. Stratified sampling
- C. Convenience sampling
- D. Systematic sampling
Answer: B
Explanation:
The best sampling method for the data analyst's need is C. Stratified sampling.
Stratified sampling is a type of probability sampling that involves dividing the population into homogeneous groups or strata based on some characteristic, such as state, and then randomly selecting a proportional number of individuals from each stratum. Stratified sampling ensures that every group is adequately represented in the sample, and reduces the sampling error and variability12 Systematic sampling is not correct, because it involves selecting every nth individual from the population, starting from a random point. Systematic sampling does not guarantee that every state will have a similar proportion of data in the sample, and may introduce bias or error if there is a hidden pattern or order in the population12 Convenience sampling is not correct, because it involves selecting individuals who are easily accessible or available to the researcher. Convenience sampling is a type of non-probability sampling that does not involve random selection, and may result in a biased or unrepresentative sample12 Random sampling is not correct, because it involves selecting individuals from the population at random, without any grouping or stratification. Random sampling may not produce a sample that has a similar proportion of data from every state, especially if the population is large or heterogeneous. Random sampling may also have a higher sampling error and variability than stratified sampling12
NEW QUESTION # 238
A data analyst has a set with more than 40.000 rows in the sample schema below: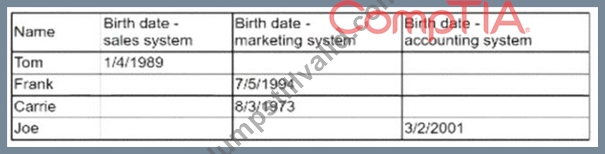
The analyst would like to create one column that contains the customers' birth dates. Which of the following data quality dimensions would BEST explain the reason for compilation?
- A. Data completeness
- B. Data duplication
- C. Data integrity
- D. Data accuracy
Answer: C
Explanation:
Explanation
Data integrity is the dimension that measures the consistency and validity of data across different data sources.
In this case, the data analyst wants to create one column that contains the customers' birth dates, but the data is stored in different formats and locations in the sample schema. For example, some customers have their birth dates in the customer table, while others have their birth years in the sales table. To compile the data into one column, the data analyst needs to ensure that the data is consistent and valid across the tables. Therefore, data integrity is the best explanation for the reason for compilation. References: Data Quality Dimensions - DATAVERSITY, The 6 Data Quality Dimensions with Examples | Collibra
NEW QUESTION # 239
Which of the following is the median of the number set:3, 7, 5, 6, 9?
- A. 0
- B. 1
- C. 2
- D. 3
Answer: C
Explanation:
Comprehensive and Detailed In-Depth
Themedianis the middle value in a sorted list of numbers. The steps to determine the median are:
Sort the numbers in ascending order:3, 5, 6, 7, 9
Find the middle value:Since there arefivenumbers, the middle value is the third one:Median = 6 Option A (5):Incorrect. 5 is not the middle value.
Option B (6):Correct.6 is the middle value in the sorted list.
Option C (7):Incorrect. 7 is not the middle value.
Option D (9):Incorrect. 9 is the highest value, not the median.
NEW QUESTION # 240
An analyst has received the requirements for an internal user dashboard. The analyst confirms the data sources and then creates a wireframe. Which of the following is the NEXT step the analyst should take in the dashboard creation process?
- A. Deploy to production.
- B. Optimize the dashboard.
- C. Get stakeholder approval.
- D. Create subscriptions.
Answer: C
Explanation:
Explanation
Getting stakeholder approval is the next step the analyst should take in the dashboard creation process, after confirming the data sources and creating a wireframe. Stakeholder approval means getting feedback and validation from the intended users or clients of the dashboard, to ensure that it meets their expectations and requirements. This step helps to avoid rework and ensure customer satisfaction. References: CompTIA Data+ Certification Exam Objectives, page 14
NEW QUESTION # 241
A data analyst for a media company needs to determine the most popular movie genre. Given the table below: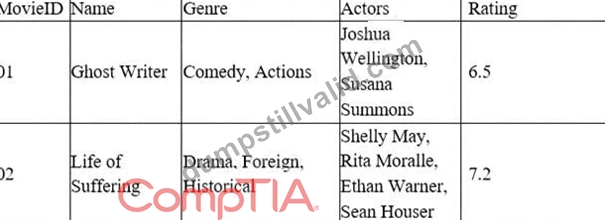
Which of the following must be done to the Genre column before this task can be completed?
- A. Delimit
- B. Concatenate
- C. Append
- D. Merge
Answer: A
Explanation:
The action that must be done to the Genre column before this task can be completed is delimit. Delimit is a process of separating or splitting a string of text into multiple parts based on a delimiter, which is a character or a sequence of characters that marks the boundary between the parts. For example, a comma (,) or a semicolon (;) can be used as a delimiter. In this case, the Genre column contains multiple genres for each movie, separated by commas. To determine the most popular movie genre, the data analyst needs to delimit the Genre column by commas, so that each genre can be counted and compared separately. The other options are not relevant for this task, as they are related to combining or joining strings or tables, not separating them.
Append is a process of adding or attaching one string or table to the end of another string or table. Merge is a process of combining or joining two or more tables into one table based on a common column or key.
Concatenate is a process of joining or linking two or more strings together into one string. Reference: [How to Split Text in Excel - Exceljet]
NEW QUESTION # 242
A county in Illinois is conducting a survey to determine the mean annual income per household. The county is
427sq mi (2.65q km). Which of the following sampling methods would MOST likely result in a representative sample?
- A. Surveys sent to ten randomly selected homes within 5mi (8km) of the county's office
- B. A systematic survey that is sent to 100 single-family homes in the county
- C. A stratified phone survey of 100 people that is conducted between 2:00 p.m. and 3:00 p.m.
- D. Surveys sent to 100 randomly selected homes that are reflective of the population
Answer: D
Explanation:
Explanation
Surveys sent to 100 randomly selected homes that are reflective of the population. This is because a random sample is a type of sample that is selected by using a random method, such as a lottery or a computer-generated number, which ensures that every element in the population has an equal chance of being selected. A random sample can result in a representative sample, which means that the sample reflects the characteristics and diversity of the population. By sending surveys to 100 randomly selected homes that are reflective of the population, the analyst can ensure that the sample is representative of the county's households and their income levels. The other sampling methods are not likely to result in a representative sample. Here is why:
A stratified phone survey of 100 people that is conducted between 2:00 p.m. and 3:00 p.m. would result in a biased sample, which means that the sample favors or excludes certain groups or elements in the population.
By conducting the survey only between 2:00 p.m. and 3:00 p.m., the analyst would miss out on people who are not available or reachable at that time, such as those who are working or sleeping. This could affect the representativeness and generalizability of the sample.
A systematic survey that is sent to 100 single-family homes in the county would result in an unrepresentative sample, which means that the sample does not reflect the characteristics and diversity of the population. By sending surveys only to single-family homes, the analyst would ignore other types of households, such as apartments, condos, or mobile homes. This could affect the accuracy and reliability of the sample.
Surveys sent to ten randomly selected homes within 5mi (8km) of the county's office would result in a small sample, which means that the sample size is too low to capture the variability and diversity of the population.
By sending surveys only to ten homes within a limited area, the analyst would miss out on many households that are located in different parts of the county. This could affect the precision and confidence of the sample.
NEW QUESTION # 243
A development company is constructing a new unit in its apartment complex. The complex has the following floor plans: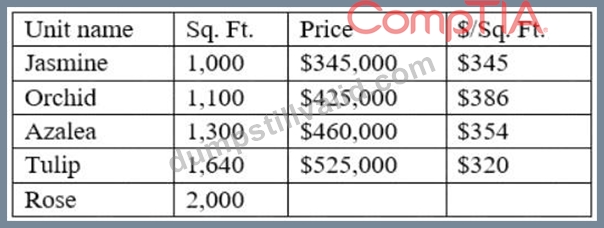
Using the average cost per square foot of the original floor plans, which of the following should be the price of the Rose unit?
- A. $702,500
- B. $690,000
- C. $640,900
- D. $705,200
Answer: D
Explanation:
Explanation
This is because the price of the Rose unit can be estimated using the average cost per square foot of the original floor plans, which are Jasmine, Orchid, Azalea, and Tulip. To find the average cost per square foot of the original floor plans, we can use the following formula:
Plugging in the values from the original floor plans, we get: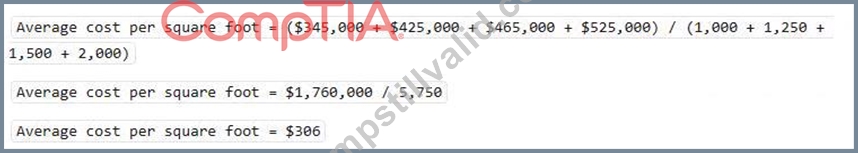
To find the price of the Rose unit, we can use the following formula:
Plugging in the values from the Rose unit, we get: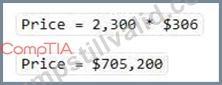
Therefore, the price of the Rose unit should be $705,200, using the average cost per square foot of the original floor plans.
NEW QUESTION # 244
Refer to the exhibit.
Given the diagram below: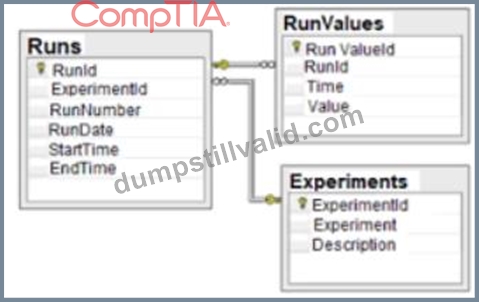
Which of the following data schemas shown?
- A. Online transactional processing
- B. Relational database
- C. Key-value pairs
- D. Data Lake
Answer: B
Explanation:
A relational database is a type of database that organizes data into tables, where each table has a fixed number of columns and a variable number of rows. Each row in a table represents a record or an entity, and each column represents an attribute or a property of that entity. The tables are linked by common fields, called keys, which enable the database to establish relationships between the data. A relational database schema is a diagram that shows the structure and organization of the tables, columns, keys, and constraints in a relational database. The diagram given in the question is an example of a relational database schema, as it shows two tables: "Runs" and "Experiments", with their respective columns, data types, and primary keys. The "Runs" table also has a foreign key that references the "ExperimentId" column in the "Experiments" table, indicating a relationship between the two tables. Therefore, the correct answer is D. Reference: What is a database schema? | IBM, Database Schema - Javatpoint
NEW QUESTION # 245
A publishing group has requested a dashboard to track submissions before publication. A key requirement is that all changes are tracked, as multiple users will be checking out documents and editing them before submissions are considered final. Which of the following is the BEST way to meet this stakeholder requirement?
- A. Display the version number next to each submission on the dashboard.
- B. Present a data refresh date at the top of the dashboard.
- C. Confirm the dashboard is adhering to the corporate style guide.
- D. Use permissions to ensure users only see certain versions of the submissions.
Answer: A
Explanation:
Explanation
A static report is a type of report that shows a snapshot of data at a specific point in time. A static report does not change or update automatically, unless the data source is refreshed or the report is regenerated. A static report is suitable for situations where the data does not change frequently or where historical data is needed for comparison or analysis. In this case, the data analyst is asked to create a sales report for the second-quarter
2020 board meeting, which will include a review of the business's performance through the second quarter.
The board meeting will be held on July 15, 2020, after the numbers are finalized. This means that the data analyst does not need to show real-time or dynamic data, but rather a fixed and accurate view of the sales data for the second quarter. Therefore, a static report would be the best way to meet this stakeholder requirement.
Therefore, the correct answer is A. References: What are Static Reports? | Sisense, Static vs Dynamic Reports
- What's The Difference? | datapine
NEW QUESTION # 246
A data analyst reviews the following data set: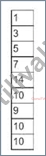
Which of the following is the range value?
- A. 0
- B. 1
- C. 2
- D. 3
Answer: B
NEW QUESTION # 247
A data analyst needs to calculate the mean for Q1 sales using the data set below: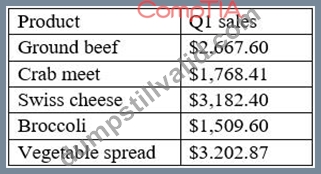
Which of the following is the mean?
- A. $3,082.72
- B. $2,466.18
- C. $2,667.60
- D. $12,330.88
Answer: A
Explanation:
The mean is the average of all the values in a data set. To calculate the mean, we add up all the values and divide by the number of values. In this case, the mean for Q1 sales is ($2,000 + $3,000 + $4,000 + $2,500 + $3,500) / 5 = $3,082.72 Reference: CompTIA Data+ Certification Exam Objectives, page 9
NEW QUESTION # 248
Exhibit.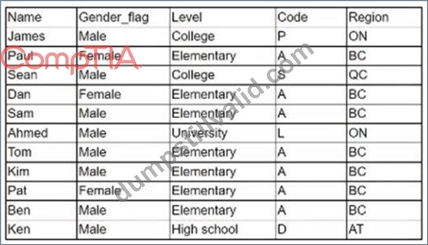
Which of the following logical statements results in Table B?
- A.

- B.

- C.

- D.

Answer: D
Explanation:
The logical statement that results in Table B is Option D. Option D is a logical statement that uses the AND operator to combine two conditions: Name = "Tom" and Region = "BC". The AND operator returns true only if both conditions are true, otherwise it returns false. Therefore, Option D will select only the rows from Table A that satisfy both conditions, which are rows 4, 5, 6, and 7. These rows form Table B, as shown below:
Name | Gender flag | Level | College | Code | Region Tom | Male | Elementary | A | BC | BC Kim | Female | Elementary | A | BC | BC Pat | Female | Elementary | A | BC | BC Ben | Male | Elementary | A | BC | BC The other options are not correct, as they use different logical operators or conditions that do not result in Table B. Option A uses the OR operator, which returns true if either condition is true, or both. Option A will select all the rows from Table A except row 3, which does not match either condition. Option B uses the NOT operator, which returns the opposite of the condition. Option B will select all the rows from Table A except rows 4, 5, 6, and 7, which match the condition. Option C uses a different condition, Region = "ON", which does not match any row in Table A. Option C will select no rows from Table A. Reference: [SQL Logical Operators - W3Schools]
NEW QUESTION # 249
......
CompTIA DA0-001 certification is vendor-neutral, which means that it is not tied to any specific technology or platform. This makes it an ideal certification for professionals who work in a variety of industries, including healthcare, finance, and government. CompTIA Data+ Certification Exam certification is also suitable for professionals who work with big data and want to gain a deeper understanding of how to manage and analyze large datasets. CompTIA Data+ Certification Exam certification exam is designed to test an individual's proficiency in data management, data analysis, and data security, and passing the exam demonstrates a high level of competency in these areas.
Latest DA0-001 Exam Dumps CompTIA Exam from Training: https://www.dumpstillvalid.com/DA0-001-prep4sure-review.html
Newly Released DA0-001 Dumps for CompTIA Data+ Certified: https://drive.google.com/open?id=1Z0rk4usXsFmA2d6-kz_9hGxirh8aJL08
